Apple is no longer a computer manufacturer, Google is no longer a search engine, and Amazon is no longer just an online shopping mall. What these companies have in common is that they conquer other areas of life from their respective starting points. The effects are already foreseeable.
In addition to the search engine, Google offers e-mail, a mobile phone operating system and mobile phones, a voice-operated assistant, a computer operating system, a browser, self-driving cars, a photo service and other services in the cloud, music, movies, home surveillance systems (Nest), YouTube and much more. Apple offers mobile phones, computers, iPads, software, a music service, a SmartWatch, headphones, a voice-operated assistant, a TV service and a cloud solution, and much more. Among other products, Amazon offers food delivery, its own products, a voice-operated assistant, video conferencing hardware, a music service, a film service and is also the largest cloud provider. And much more.
At first glance, the services may each be a colorful potpourri, but if you take a closer look, the three big digital heavyweights (Facebook excluded from the GAFA acronym) are tinkering with life operating systems. Our lives will increasingly be supported by digital systems, and Apple, Amazon and Google are working to make as much of these systems available as possible. A system that links digital life coherently and coherently could be called a life operating system.
This is especially evident when you want to switch from one system to another or have to exchange data with another system. This is already difficult in some cases. Android phone and MacBook? It’s no fun. Switching from an Android to an Apple phone? No problem at first, there is an assistant. But the calendar? And the contacts? How do I get the photos into Apple’s elegant Photos app? It is only really efficient when all digital activities are designed with Apple products. Photos sync across multiple devices, as do files, no matter how much storage space you have on each device.
At Google, the assistant learns. The more Google products are used, the better suggestions are generated. Traffic jam on the way to work? No problem, the Android phone warns its user based on historical data and the current traffic situation. Here, too, synchronization is carried out across several devices.
Amazon still seems to be lagging behind. But the strategy of selling hardware at a discount, as in the case of tablets, helps to bind customers to the Amazon universe.
And so a new class society could soon arise, which could result from the use of the respective life operating system:
Those who can afford it use the Apple system. It’s expensive, but time-saving and chic.
The Google system will be somewhat cheaper, even if Google tries its hand at the upper price segments with the Pixel devices. It is the system for the masses.
The cheapest will be an Amazon system. It doesn’t offer the fastest hardware, but everything you need is included.
Those who want to remain independent work with Linux computers and free software. The rebels. They pay primarily with lifetime, but also retain control over their data.
However, it will only get really exciting when the AI-based assistants are really good. If they can then use all the information they collect about a user via several different services, then real support like in “Her” would only be possible. And then it will be even harder to switch from one system to the next.
But perhaps the Internet giants will open up and provide each other with interfaces. Siri could learn from Gmail and Alexa from the YouTube playlist. But that doesn’t sound very likely. Instead, it looks more like we will be trapped in the respective systems because switching would bring too many disadvantages.
This also has very practical implications: What if an Apple woman wants to move in with an Amazon guy? It cannot control its hardware and vice versa. Or will there be no more dating between classes?
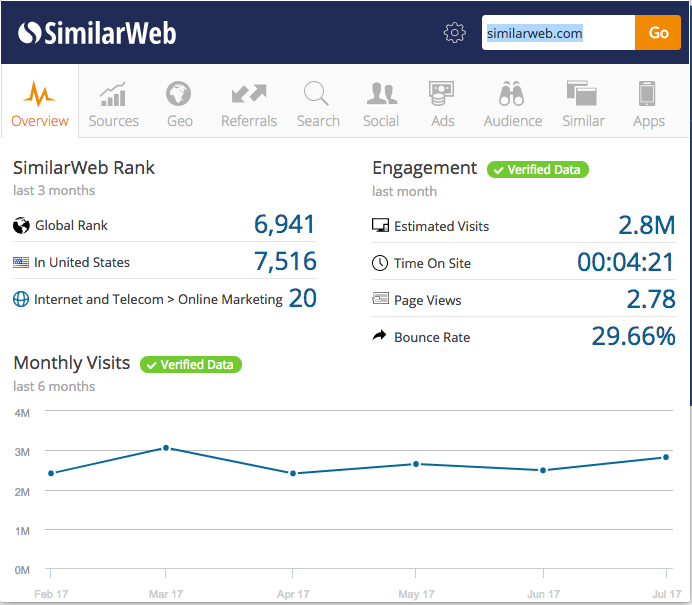
As with Google Trends, I’m always surprised at how quickly conclusions can be drawn from data without having to think about where the data actually comes from and how plausible it is. Especially with Similar Web, this is amazing, because Google has the search data and can read trends from it, but how can Similar Web have data about how many visitors a website or app has? How reliable is this data? Is the reliability sufficient to make important business decisions?
The ancestor of SimilarWeb
In 2006, my former colleague Matt Cutts had once investigated how reliable Alexa’s data is (Alexa used to be an Amazon service that had nothing to do with speech recognition). This service collected data with a browser toolbar (there’s no such thing anymore), i.e. every page a user looked at was logged. Since Alexa was especially interesting for webmasters, pages that are interesting for webmasters were logged. So they were distorted. So if you are already recording the traffic of users, then you have to somehow make sure that the user base somehow corresponds to the network population you want to find out about. That doesn’t mean that the data is completely worthless. If you compare two fashion sites with each other, then they are probably “uninteresting” for the webmaster population (a prejudice, I know), and then you could at least compare them with each other. But you couldn’t compare a fashion page with a webmaster tool page.
But where does Similar Web get the data from? On their website they give 4 sources:
An international panel
crawling
ISP data
direct measurements
Data collection via a panel
The panel is not explained in detail, but if you do only minimal research, you will quickly find browser extensions. These are probably the successors of the earlier browser toolbars. What is the advantage of the Similar Web Extension? It offers exactly what Similar Web offers: You can see with one click how many users the currently viewed page has, where they come from, and so on. The Similar Web-Extension does not only work at home if you are currently viewing the data for a page, but for every page you are viewing.
If you consider for whom such data is interesting and who then installs such an extension, then we have arrived at the data quality of the Alexa Top Sites. Webmasters, marketing people, search engine optimizers, all these people have a higher probability to install this extension than for example a teenager or my mother.
Crawling
What exactly Similar Web crawls is still a mystery to me, especially why a crawling can give information about how much traffic a page has. Strictly speaking, you only cause traffic with a crawler Similar Web says, “[we] scan every public website to create a highly accurate map of the digital world”. Probably links will be read here, maybe topics will be recognized automatically.
ISP traffic
Unfortunately, Similar Web does not say which ISPs they get traffic data from. It’s probably forbidden in Germany, but in some countries it will certainly be allowed for an Internet service provider to have Similar Web’s colleagues record all the traffic they receive through their cables. That would of course be a very good database. But not every ISP is the same. Would we trust the data if, for example, AOL users were in it (do they still exist at all)?
Direct measurements
This is where it gets exciting, because companies can link their web analytics data, in this case Google Analytics, directly to Similar Web, so that the data measured by Google Analytics is available to all Similar Web users. Then the site says “verified”. Why should you do that? You don’t get anything for it, instead you can expect more advertising revenue or strengthen your brand. Quite weak arguments, I think, but there are still some sites that do.
How reliable is Similar Web data really?
Of course, the direct measurements are reliable. It becomes difficult with all other data sources. These make up the majority of the measurements. Only a fraction of the Similar Web data is based on my sample of direct measurement data. But here you could certainly create models based on the accurately measured data and the inaccurately measured data. If I know how the data from spiegel.de is accurate and what the inaccurately measured data looks like, then I could, for example, calculate the panel bias and compensate for other pages. And I could do the same with all other data.
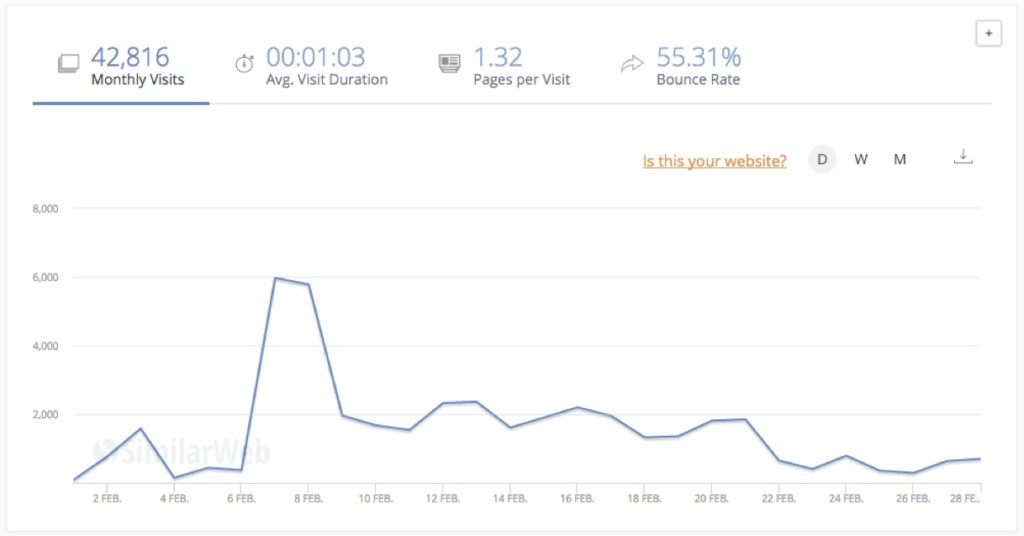
But does it really work? Let’s take a look at a measurement of Similar Web for one of my pages:
Apparently the number of visitors fluctuates between as good as nothing and 6,000 users. There are no clear patterns. And now we look at the real numbers from Google Analytics:
It’s the same time period. And yet the unique traffic patterns from the Google Analytics data are not recognizable in the Similar Web data. The data is simply wrong.
Result
Can you use Similar Web at all? I would advise you to be very careful if the data does not come from a direct measurement. Of course, the question can now arise as to what else to use. The counter-question is what to do with data that you can’t be sure is correct at all. If I had to make a business decision that might cost a lot of money, I wouldn’t rely on that data. For a first glance…? We also know that a “first glance” can quickly become a “fact” because it fits so well into one’s own argumentation.
In their 2017 book “R for Data Science“, Grolemund and Wickham state that data.table is recommended instead of dplyr when working with larger datasets (10 to 100 Gb) on a regular basis. Having started with Wickhams sparklyr (R’s interface to Spark using the dplyr dialect), I was wondering how much faster data.table actually is. This is not the most professional benchmark given that I just compare system time before and after the script ran but it gives an indication of the advantages and disadvantages of each approach.
My work includes dealing with larger files almost every day, and for this test, I have used a 16 GB CSV file with 88.956.866 rows and 7 columns. After reading the file, I will do a few simple operations with that data and then write the result back to disk. The test is performed on an AWS EC2 m4.2xlarge instance with 32 GB of RAM and 8 vCPUs of which we will use 4. Let’s start with data.table:
`
library(data.table)
overallStart_time <- Sys.time()
start_time <- Sys.time()
userDataSetDT <- fread(“/home/tom/huge-file.csv”)
Read 88956065 rows and 7 (of 7) columns from 15.969 GB file in 00:02:52
end_time <- Sys.time()
end_time – start_time
Time difference of 6.507585 mins
`
I have no idea why fread says it only needed 2:52 minutes; there were no other CPU-hungry processes running or processes that had a huge impact on IO.
`> start_time <- Sys.time()
userDataSetDT <- userDataSetDT[!is.na(Timestamp)]
end_time <- Sys.time()
end_time – start_time
Time difference of 39.44712 secs
start_time <- Sys.time()
userDataSetDT <- userDataSetDT[!is.na(URL)]
end_time <- Sys.time()
end_time – start_time
Time difference of 38.62926 secs
start_time <- Sys.time()
configs <- userDataSetDT[configSection == “Select Engine”]
end_time <- Sys.time()
end_time – start_time
Time difference of 2.412425 secs
start_time <- Sys.time()
fwrite(configs,file=“configsDT.csv”, row.names = FALSE)
end_time <- Sys.time()
end_time – start_time
Time difference of 0.07708573 secs
overallEnd_time <- Sys.time()
overallEnd_time – overallStart_time
Time difference of 8.341271 mins`
data.table uses only one vCPU or one core respectively by default but consumes more virtual memory (43GB instead of 13GB being used by the R/sparklyr combination). We could use packages such as the parallel one but in fact, data.table is a bit more complex with respect to parallelization.
end_time <- Sys.time()
end_time – start_time
Time difference of 0.001763344 secs
start_time <- Sys.time()
collected <- collect(configs)
end_time <- Sys.time()
end_time – start_time
Time difference of 1.333298 mins
start_time <- Sys.time()
write.csv(collected, file=“configs.csv”, row.names = FALSE)
end_time <- Sys.time()
end_time – start_time
Time difference of 0.01505065 secs
overallEnd_time <- Sys.time()
overallEnd_time – overallStart_time
Time difference of 3.878917 mins
“
We have saved more than 50% here! However, looking at the details, we see that collecting the data has cost us a lot of time. Having said that, doing the selects is faster on sparklyr compared to data.table. We have used 4 vCPUs for this, so there seems to be an advantage in parallelizing computing the data, there is almost no difference in writing the data, also given that data.table’s fread has been highly optimized. Edit: As one commenter said below, you would probably not collect the whole dataset and rather let Spark write the CSV but I have not done to make the approach more comparable.
If we used only one core for sparklyr (which doesn’t make any sense because even every Macbook today has 4 cores), how long would it take then?
`> start_time <- Sys.time()
userDataSet <- spark_read_csv(sc, “country”, “/home/tom/huge-file.csv”, memory = FALSE)
end_time <- Sys.time()
end_time – start_time
Time difference of 4.651707 mins
end_time <- Sys.time()
end_time – start_time
Time difference of 0.002915621 secs
start_time <- Sys.time()
collected <- collect(configs)
end_time <- Sys.time()
end_time – start_time
Time difference of 4.487081 mins
start_time <- Sys.time()
write.csv(collected, file=“configs.csv”, row.names = FALSE)
end_time <- Sys.time()
end_time – start_time
Time difference of 0.01447606 secs
overallEnd_time <- Sys.time()
overallEnd_time – overallStart_time
Time difference of 8.345677 mins`
The selects are a bit slower albeit not noticable. sparklyr is much slower though when it comes to reading large files and collectiong data with only one core. Having said that, as mentioned above, there is no reason to use only one core.
However, there is still a good reason to use data.table: As you can see in the config file of the sparklyr code, a huge chunk of memory had to be assigned to the collector and the driver, simply because the computation or the collection will throw errors if there is not enough memory available. Finding out how much memory should be allocated to what component is difficult, and not allocating the right amount of memory will result in restarting R and running the code again and again, making data.table the better choice since no configuration is required whatsoever. In addition, it is amazing how fast data.table still is using one core only compared to sparklyr using 4 cores. On the contrary, running the same code on my Macbook Air with 8 GB RAM and 4 cores, data.table had not managed to read the file in 30 minutes whilst sparkly (using 3 of the 4 cores) managed to get everything processed in less than 8 minutes.
While I personally find dplyr a bit more easy to learn, data.table has caught me, too.
In September 2015, I stood on a big stage for Google in Berlin and showed the advantages of the new features of Google Trends in addition to voice search. It is a useful tool, but also offers a lot of potential for misunderstandings, which should be cleared up here. Search queries are enclosed in <> parentheses.
1. Misconception: Not all search queries are taken into account
2. Misconception: There are no absolute numbers
3. Misconception: A search query is different on Google Trends
4. Misconception: A rising line does not mean that searches were made more often
5. Misconception: Without a benchmark, Google Trends is worthless
Bonus Misconception and Effects of Misinterpretations
How can Google Trends be used sensibly?
Summary
This text was updated on May 27, 2020, because Google had revised the help for Google Trends.
1. Misconception: The basis of Google Trends data
Google Trends is not based on all search queries entered on Google, but on a representative sample:
Google Trends data reflects the search queries that users make to Google every day. However, they may also include irregular search activity, such as automated searches with the aim of distorting our results. […] Although we have mechanisms in place to detect and filter such activity, these searches are sometimes stored in Google Trends for security reasons: If we were to filter them out in principle, the creators of such queries would know that we are tracking them. This in turn would make it more difficult to filter out such activities from other Google search products, where the most accurate representation of the real data is crucial. For this reason, users of Google Trends data should understand that it is not an accurate reflection of search activity.
Google Trends filters out certain types of search queries, for example […] Searches from a few people: Trends only analyzes data for popular search terms. Terms with low search volume therefore appear as 0
There is no definition of when a term is popular. And just by the way: Hasn’t anyone noticed that hormone-controlled terms never appear in the most popular search terms published in newspapers based on Google Trends? The first insight: We are talking about trends here, no more and no less.
2. Misconception: Lines and search volumes – There are no absolute numbers
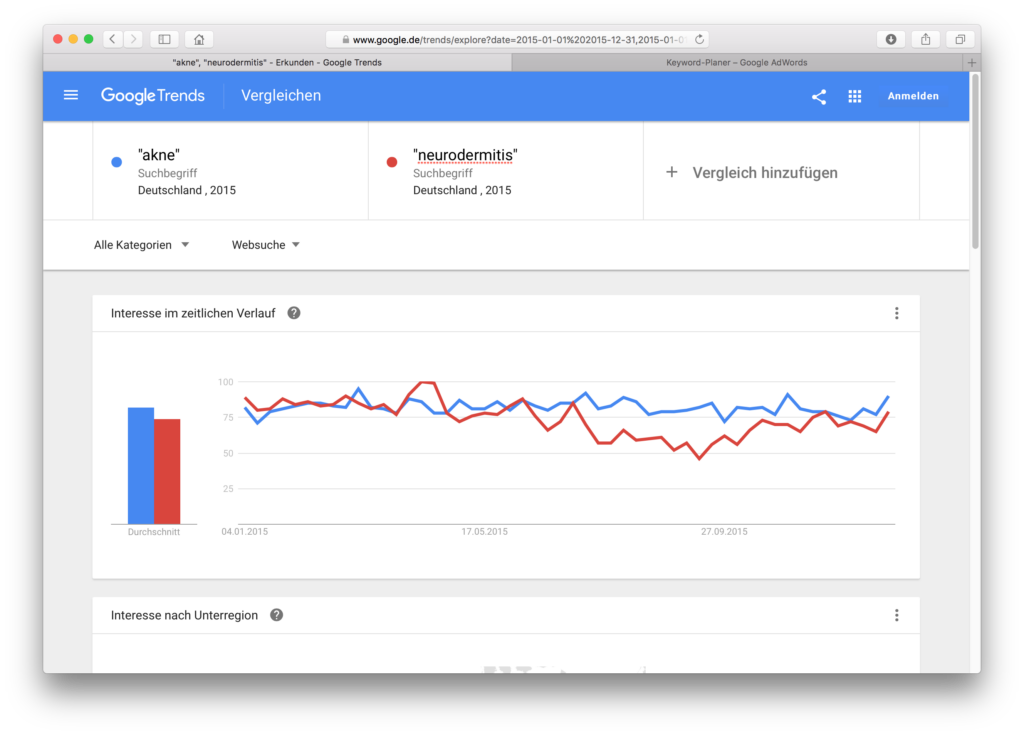
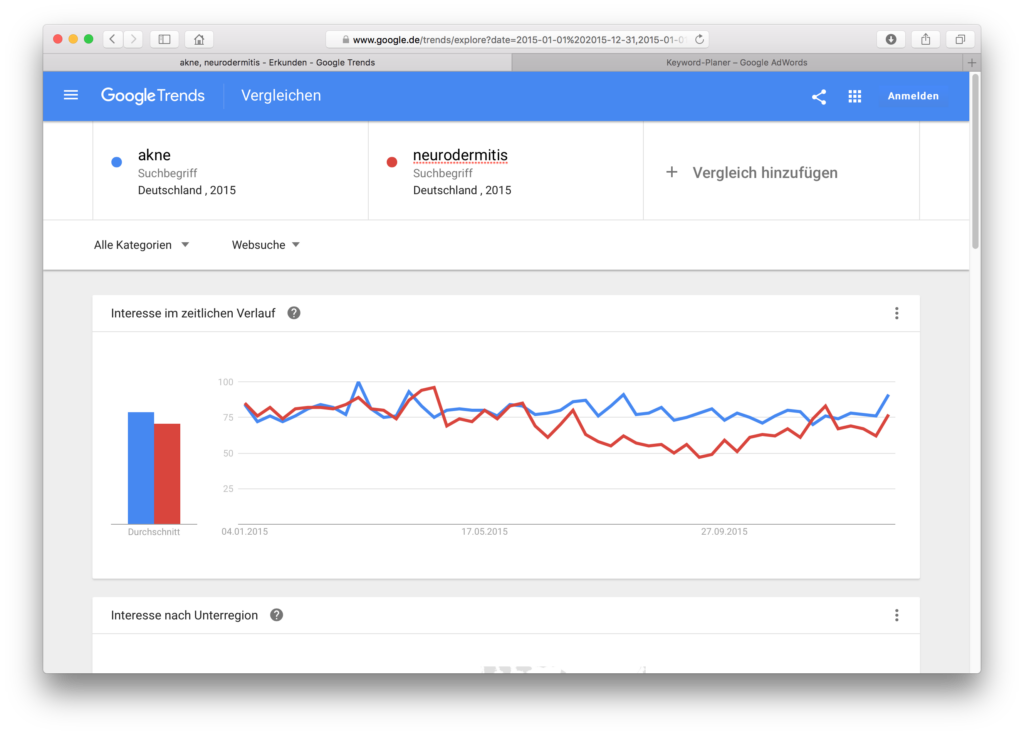
This is the biggest and the most fatal misunderstanding. If one curve is above the other, this does not mean that one term was searched for more often than the other. The lines do not reflect absolute numbers. In this example, we are looking for acne and neurodermatitis (I explain below why I write this in quotation marks in the mask) for the country of Germany in 2015. Acne and neurodermatitis alternate in search interest, but acne seems to have a higher search interest more often:
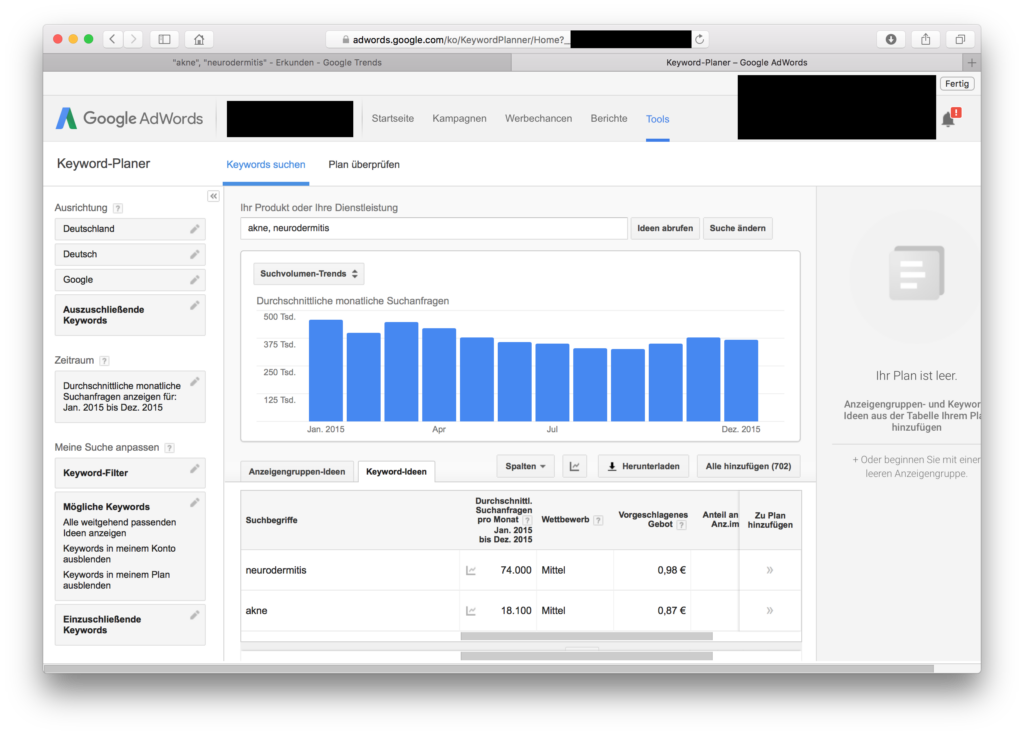
And then I look at the data in Google AdWords Keyword Planner, for the same time period, for the same country:
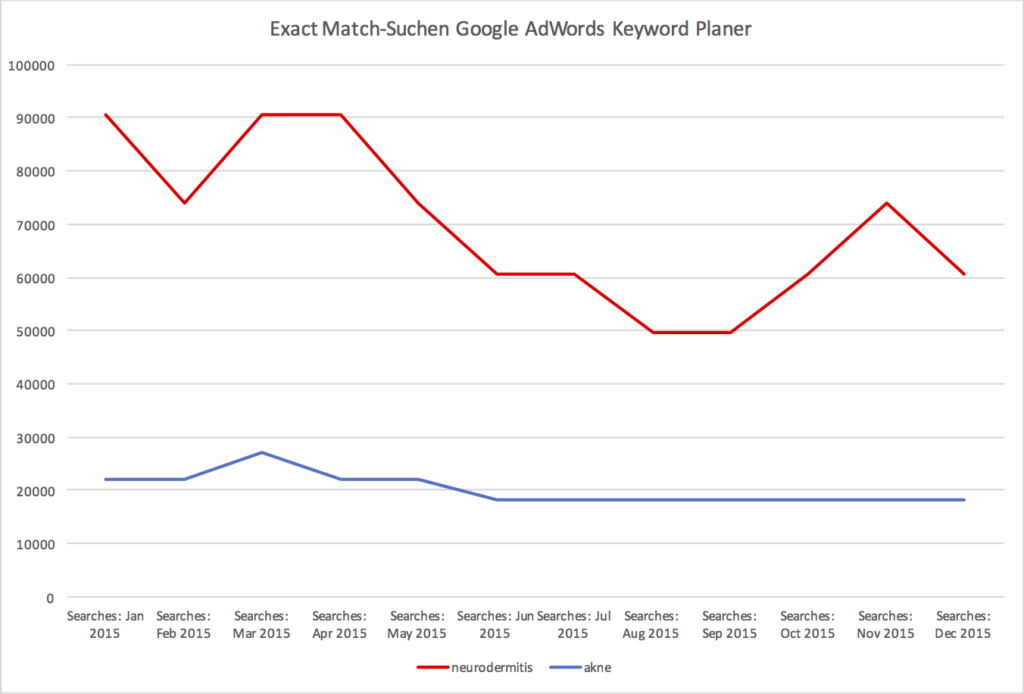
What is interesting here is not the graph (I only took the screenshot so that you can see that I am searching in the same country for the same period), but the two lines below where we see the average search volume per month. Atopic dermatitis is far above acne, 74,000 to 18,100.
Averages can lead us in the wrong direction, so let’s also look at the data plotted for each month:
We see a similarity to the Google Trends graphic, namely that searches for neurodermatitis go down from May or middle of the year and up again from September. And, this will be important later, neurodermatitis gets around 100 on Google Trends, but acne never reaches this point. Otherwise, the curves of the AdWords data do not touch once as in Google Trends. They are far apart. So the second insight: We can’t claim from Google Trends data that one term is searched for more often than another (although Google Trends is often misused for this). Google Trends doesn’t offer absolute numbers. Sorry.
3. Misconception: What is a search query?
If you type in Google or in the Google AdWords Keyword Planner, you will only search for this term. If you enter trends on Google, it will automatically search for other terms, even if you have not selected a topic, but only this search term (see the [Help][4]). For example, you can restrict something by putting a term in quotation marks (“acne cream”), but this only restricts that it is not searched for, but it could be included. It is not said which search terms are included. An “exact match” does not exist, see again [the help][5].
Let’s take a look at the differences:
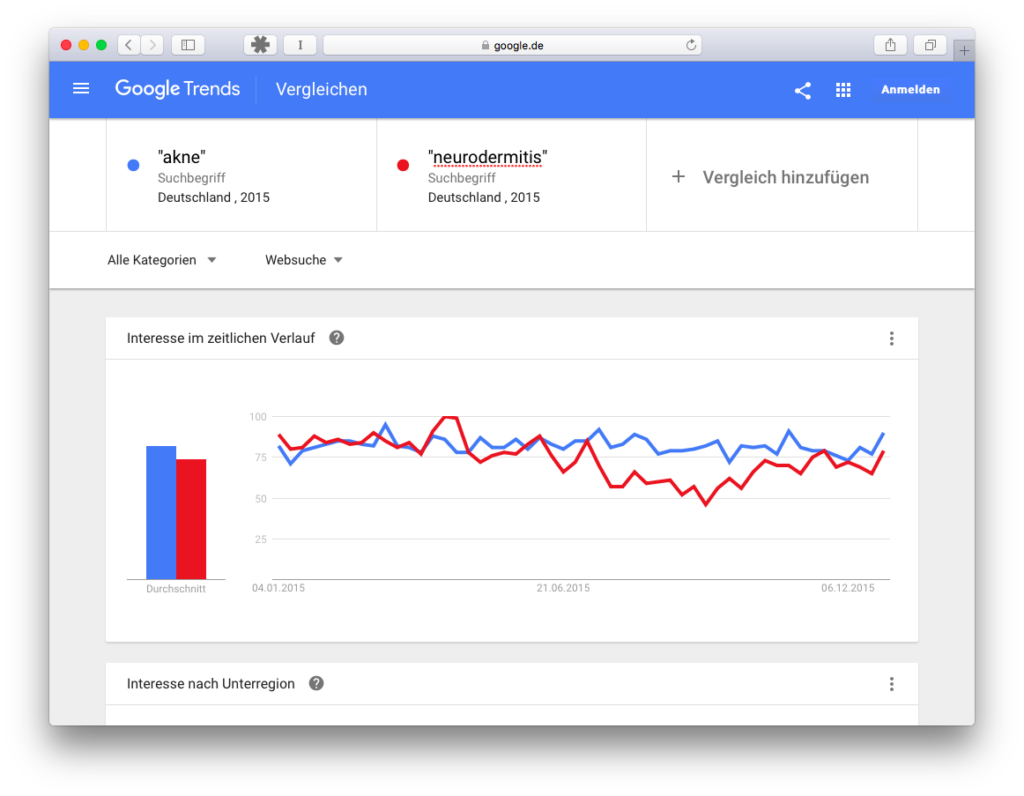
In this example, we compare the search terms and . If we add quotes, then the curves will look a little different:
Not a huge change, but there is a difference that we will remember again for later: If we enter the terms without quotation marks, then we get about 100, with quotation marks we get about 100.
It is surprising, because in the case of a one-word term, where no synonyms are searched, there can be no different order for the words in the search query. We cannot explain this phenomenon.
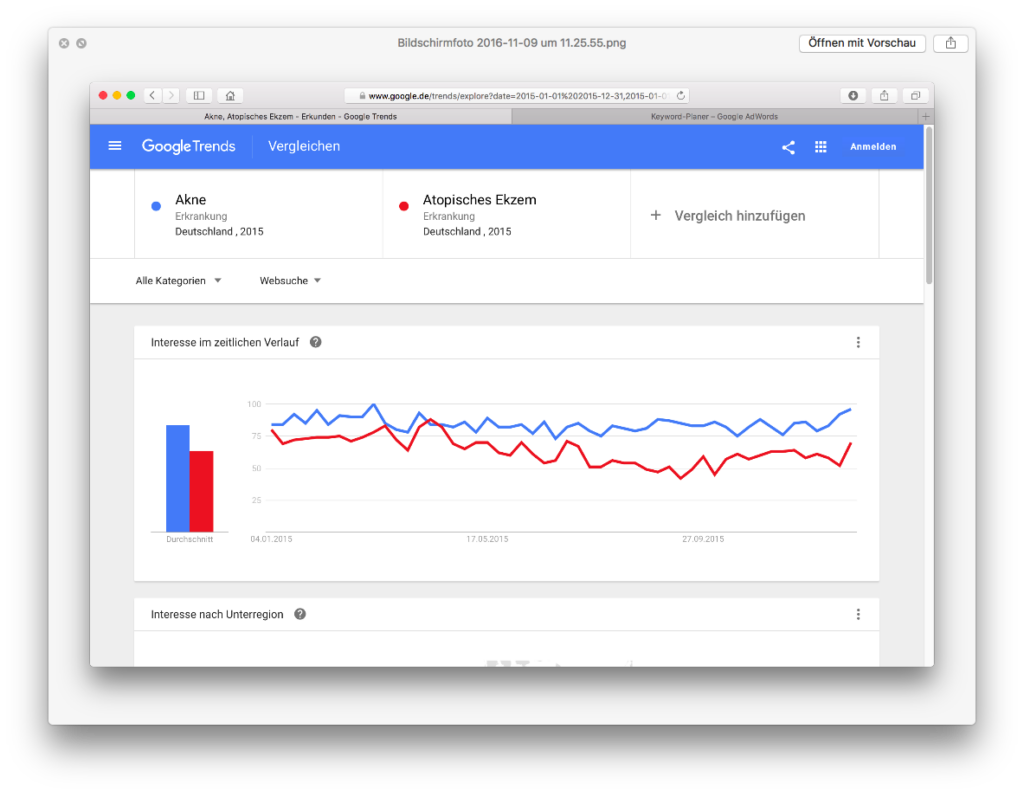
Finally, let’s take a look at what happens when we select the automatically identified topic “disease” (note: Google automatically makes out what the medical term for atopic dermatitis is):
Here, the trend data of terms that fit into the group of the disease are aggregated. The “search interest” in neurodermatitis comes close to the topic of acne in February 2016, but acne as a topic seems to have a greater search interest than neurodermatitis. Again, we don’t know which terms are grouped together. So it could be that the different data comes from the fact that Google Trends includes additional terms for both terms, but for the term acne terms are used for terms whose search interest is different and therefore changes the result. But that doesn’t sound very plausible. Third finding: Google Trends data is not comparable to AdWords data because the input is interpreted and enriched differently and we at Google Trends don’t know what it is with.
However, the differences between AdWords and trends are probably still not explained. What could be other reasons?
4. Misconception: Anything that rises or falls is a trend in Google Trends
Now it’s getting a bit mathematical. Google Trends does not offer absolute numbers, all data is displayed on a scale from 0 to 100. And now we remember the two clues above again, when one of the two search query curves touched the 100. Touching the 100 has a lot of meaning, because everything else is calculated from this highest point of search interest!
But it gets even more complicated: First of all, search interest is the search volume for a term divided by the search volume of all terms. Since we don’t know the basis (i.e. how many searches there were in total on that day) and this basis changes every day, it is possible that the line of search interest for a term changes, even though this term is searched for the same number of times every day. The point at which the maximum of this search term/all search terms ratio is reached becomes the maximum, i.e. 100 in the Google Trends chart, and all other values, including those of comparison terms, are derived from it in a normalized manner. And only for the selected period. If this is changed, the maximum is also recalculated. This leads to differences that could lead you to choose exactly the period that suits what you would like to sell Examples:
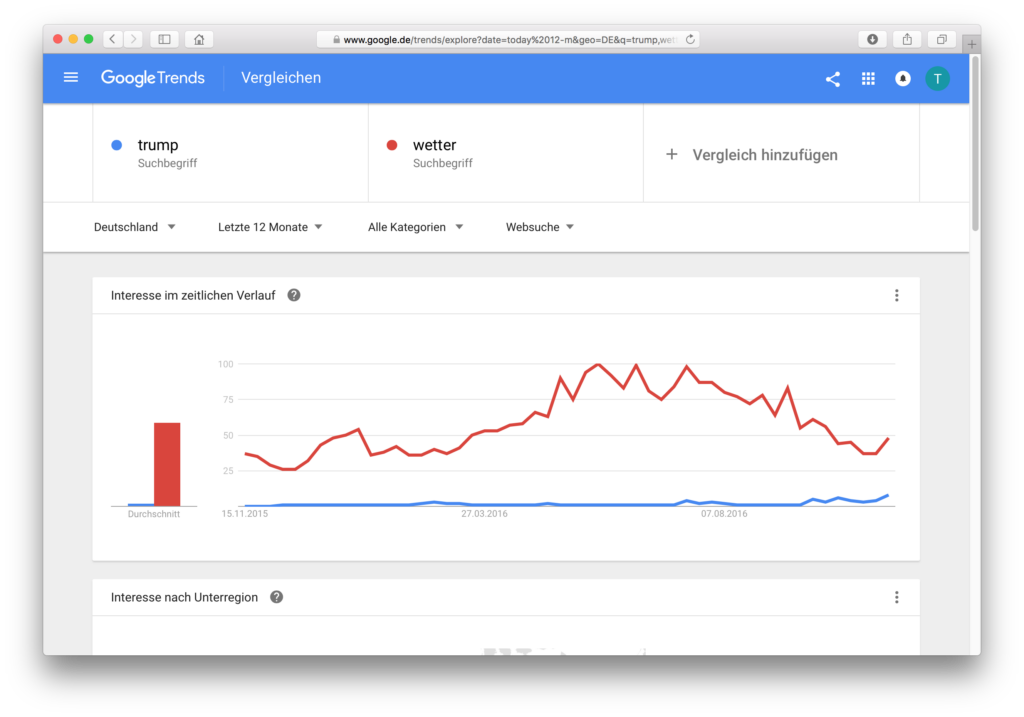
Misinterpretation: Compared to the weather, interest in Trump has hardly increased in the last 12 months
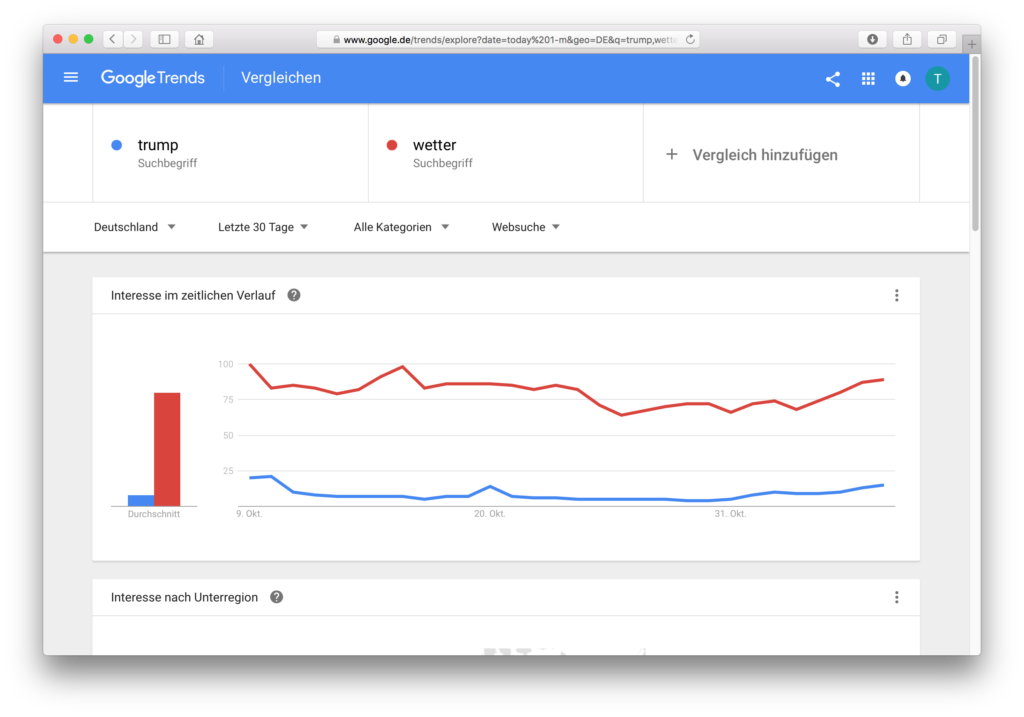
Misinterpretation: In the last 30 days, interest in Trump has not increased as much as that in Wetter. In fact, however, the data from Google Trends has not yet been updated, the election day and the previous day are missing.
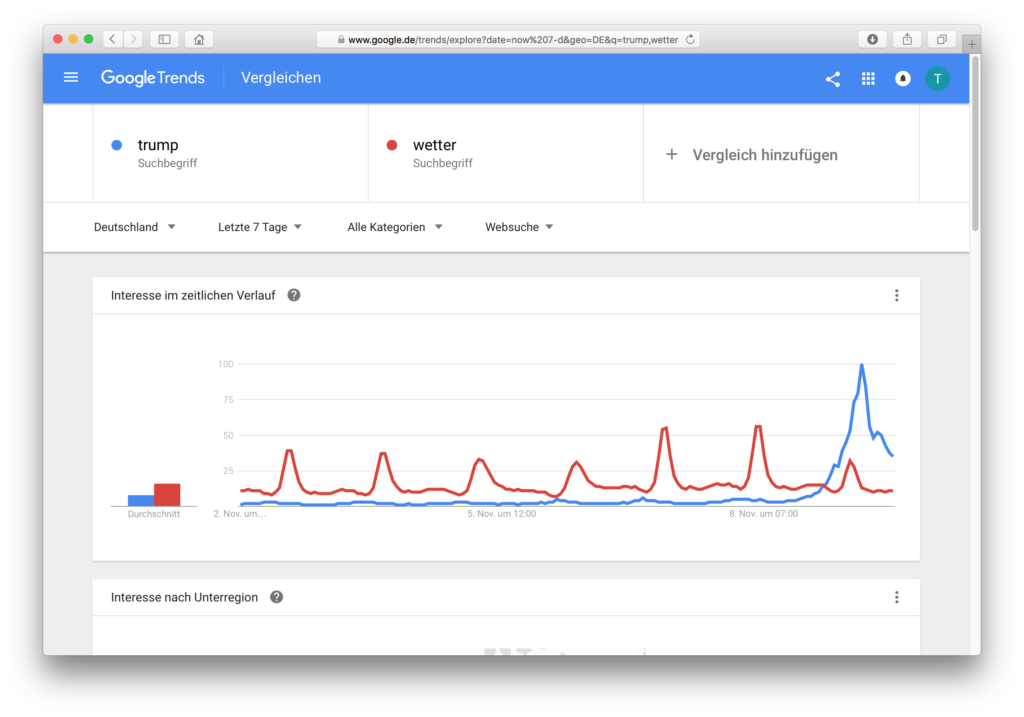
The chart for the last 7 days: Can we now claim that Trump was searched for more often than the weather?
These last graphs are very nice because they plausibly show that the Germans did not necessarily search less for the weather, but the search queries for the term Trump on 9.11 had a significantly higher proportion in the population of all searches compared to the 6 days before. Everything else is calculated from this one maximum. Over 30 days, however, the weather had a maximum (EDIT: Because the day after the election was not yet possible and it is not even two days later! Thanks to Jean-Luc for this hint!), and then the calculations are made from there. That’s why this data can be so different.
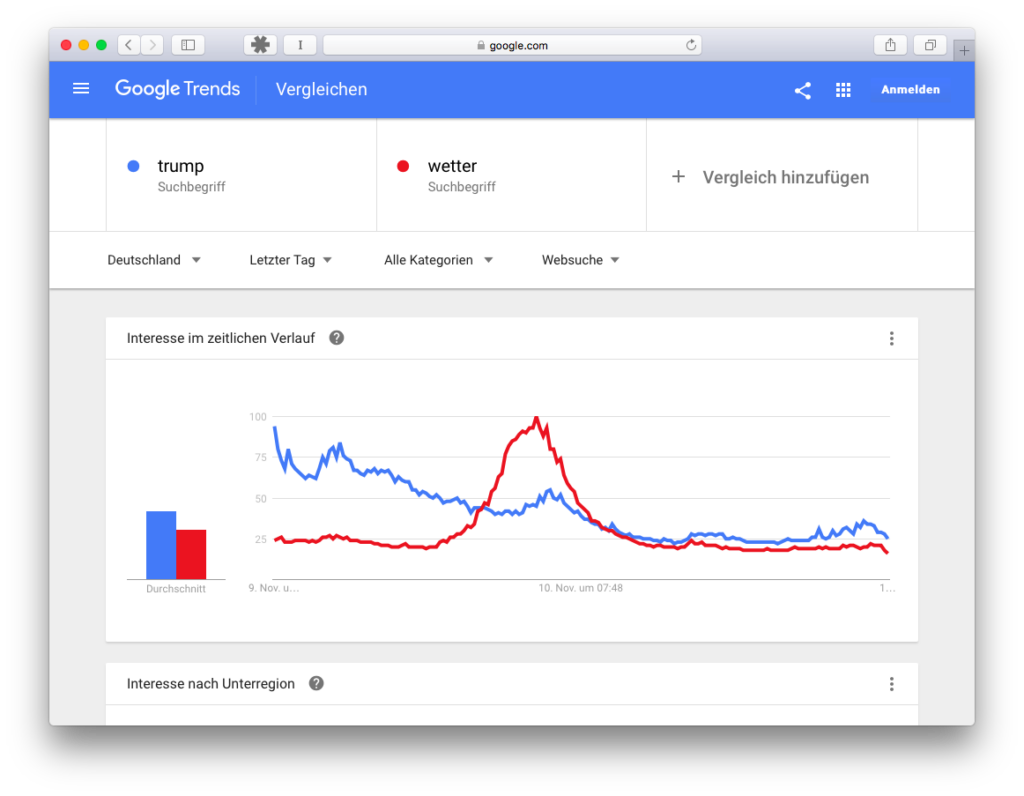
Edit: If you look one day after the election and only look at the last day (i.e. data that is about 10 minutes old), then the result looks like this:
Again, the weather is higher, although Trump comes close. Or? Well, I took this screenshot in the evening, and the peak of Trump searches probably took place more than 24 hours ago. It is very likely that I would have gotten a different image if I had made the same query this morning.
What do we take away from this misunderstanding?
The period of observation is immensely important, and you should not believe any trends chart without looking at several time periods
All observations start from the maximum and can then be seen relatively from this maximum, but at the same time depend on the total volume of all search queries, which we do not know.
It may not be so obvious in the graphs, but the 7-day graph is calculated on an hourly basis, the 30-day graph on a daily basis, the 12-month graph on a weekly basis. The Google AdWords Keyword Planner delivers data on a monthly basis. This is another reason why the data are not comparable.**
Learning: “The last 30 days” does not necessarily mean that the last 30 days are really in it
5. Misconception: Without a benchmark, Google Trends is worthless aka Everything that rises or falls is a trend in Google Trends, Part 2
Depends on how you define trend. After the Brexit vote, a journalist found out through Google Trends that the British had only googled what Brexit meant after the vote, many newspapers wrote about it, and only [after a data analyst had looked at what was really happening][13] did everyone row back. Yes, there was more searching for it, based on… see the 4th misconception But compared to a popular search query, there was only a twitch. Data must always be put into context to get a sense of what that really means. Although I’m not a football fan, I like to use the search query, but also to see how relevant a term really is.
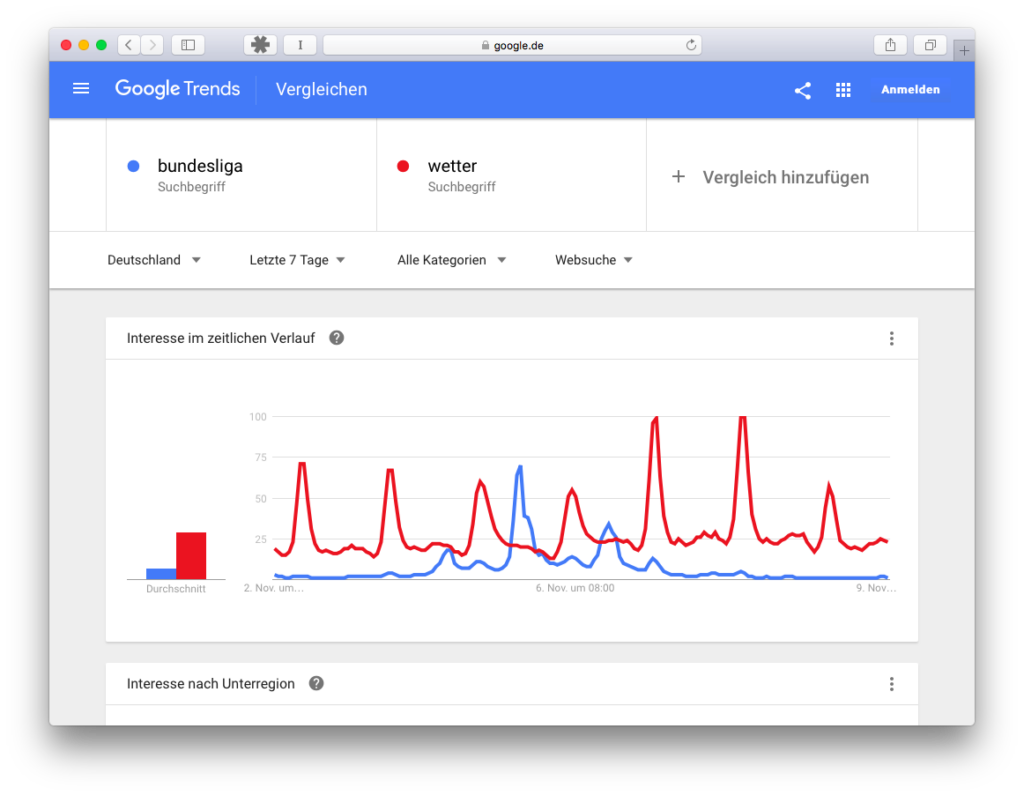
The weather is always sought, but a certain seasonality can also be observed here, Bundesliga is primarily sought by a part of the population, and only seasonally, but interesting observations can also be made here.
We can see the Friday game (first small dent in the blue curve), the Saturday games (biggest dent in the blue curve) and then again smaller dents for the Sunday games. The weather here has the highest swings, especially on Monday and Tuesday (maybe because of the snow?). So was the weather searched for more often? No, not necessarily! Since this is calculated on an hourly basis, everything is calculated from the maximum on 8.11., 5 and 6 o’clock, at this time the search interest (search query/all search queries) was highest, and everything else is calculated relatively. So it may theoretically be that on Saturday afternoon more searches for Bundesliga were carried out than for Wetter on 8.11., but the total population of search queries was higher! What do we take with us? We always need a reference point, a benchmark, something to compare search interest to. And best of all, we also know something about this point of reference, such as in this case that it snowed and there were outliers because of it.
6. Bonus Misconception and Effects of Misinterpretations
A big misconception, apart from how Google Trends works, is the assumption that users really only search for EVERYTHING on Google. For example, Google has lost some search queries to Amazon, and if you look at your own search behavior, you no longer go to Google for every search, but directly to where you know that you will immediately find what you are looking for. Be it the bookstore around the corner with an online ordering service, be it the pizza service or clothing store. In fact, some trends are not even reflected in Google tools because they take place on Pinterest and other platforms. So Google search queries cannot be used to infer the needs and wishes of all people.
What bad things can happen if you misinterpret the data? My experience shows that in the worst case, it is better to take wrong data than to have none at all. As a result, budget decisions may be made incorrectly. But it can get worse. If, for example, scientific articles use Google Trends, here for analyses in the financial market or here in health research, without understanding how the tool works. If scientists don’t even understand this or don’t take the time to check how it works, how can you ask the average user to do that? The journalism example has already been described in the previous section, and here too one would expect journalists to do a little more research. Mark Twain is said to have once said:
Never let the truth get in the way of a good story.
7. How can Google Trends be used sensibly?
If you need absolute numbers, you can only use the Google Ads Keyword Planner. Point. Alternatives such as keywordtool.io or tools with an integrated search index such as Sistrix only provide partially correct data.
So what does Google Trends have that Google Ads Keyword Planner doesn’t? Google Trends is incredibly up-to-date, data is in within a few minutes. You can understand the search interest of the past on an hourly basis. And for more than 10 years, unlike Keyword Planner, where it’s only the last 4 years.
Google Trends can therefore be used very well in combination with the Keyword Planner, for example, to understand when are the best times to control campaigns more.
Summary
The mechanism “I enter two terms in Google Trends and see which one is more popular” simply does not work that easily. This will be difficult to get out of people’s heads, because the interface is wonderfully intuitive and literally tempts you to this interpretation, and it is not completely wrong. It is difficult when decisions with serious consequences are to be made on the basis of this data, and additional data is necessary here. Keyword Planner data is no longer available to everyone, but it is not directly comparable anyway, because Google Trends data does not compare pure terms.
And yet Google Trends is more than just a gimmick. With all the above, you just have to invest a little more brainpower to build a real story out of it.
Comments (since February 2020 the comment function has been removed from my blog):
Jean-Luc Winkler says
November 2016 at 18:18 Hey Tom, very exciting post! In paragraph 4, you look at the data “last 30 days” and “last 7 days”. The data of the display “last 7 days” includes 7×24 hours from today’s last full hour retroactively (e.g.: on 09.11. at 17:17 is the last data record from 09.11. at 17; 00h). This period includes 09.11., when the curve shows the strong maximum. The data of the presentation “last 30 days” include 29 daily rates, starting from the day before yesterday retroactively (e.g. considered on 09.11., the last data point is 06.11.). So the day on which the curve shows the maximum on 11/9 is only shown in the “last 7 days” plot, not in the “last 30 days” plot, right? So let’s wait until the day after tomorrow and see if there is a deflection in the curve in relation to the curve that exceeds the curve. Best regards, Jean-Luc
Tom says
November 2016 at 20:44 Very good point, I’ll add that!
Olaf Kopp says
November 2016 at 11:23 Hi Tom, thank you for this very enlightening post. I’ve come across the differences between Keyword Planner and Google Trends several times now. I find it very annoying that Google is very opaque here and, as with other things, not consistent when it comes to data bases and more…
Tom says
November 2016 at 11:33 Hallo Olaf,
in fact, (almost) everything is explained in the help, but hardly anyone bothers to read it because it looks so easy
LG
Tom
A>utonomes Trading says 18. March 2017 at 22:13 enter a fixed start date and a variable end date in the trend and download it in the CSV and compare it. The data changes back and forth “percentage-wise” as the mood takes you. And if, for example, you only download 14 days, the sum from Sunday to Saturday, you should get the same percentage difference as with the weekly data. So the time of the data query is also decisive for the same data set. (historcial random statistic dates)
S>argon says 3. April 2018 at 18:51 Thank you! I was just amazed how search volume suddenly fell far below 100, after I had already almost finished for the keyword page… Now I know where all the people have gone!
Wallets, wallets or purses, no matter what you call it, I have had a deep aversion to them for years. I can’t carry it cool in my back pocket, so I can’t sit, which may also be due to my lack of sitting flesh. And if you want to go out in the evening, I never know where to put it: If I have it in the back, it’s stolen from me, it looks stupid in the front, and apart from that it bothers me. Exactly for people like me, there is now the solution, and she calls herself Jimi.
The Jimi Wallet is not a normal wallet, but a nice little plastic box that has a compartment for banknotes and one for one or two cards, for example EC card and driver’s license. If you press on one side of the box, it opens, and you can also simply fold it up again. Supposedly, the shutter lasts 1 million times open and close. That would be more than 100 years (with opening and closing 20 times a day). Small change: No. Identity card: No. Customer cards: No. Fits well in one of the front pockets, where it’s hard to steal anything, and besides, the small box doesn’t get in the way. Ideal for going out in the evening, because that’s all you need. Also go into town for the afternoon. Or… Actually, you can almost always limit yourself, because do you always have to have 10 different loyalty and bonus cards, credit cards, receipts of your last purchases, etc. with you?
Nice idea. I would have liked to have had it earlier.